EveryDev.ai
Subscribe
Home
Tools

4,741+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents3426
  • Coding2391
  • Infrastructure1055
  • Projects732
  • Marketing662
  • Research612
  • MCP593
  • Analytics538
  • Design533
  • Testing420
  • Security410
  • Data358
  • Prompts260
  • Integration256
  • Communication250
  • Extensions222
  • Voice201
  • Learning193
  • Commerce173
  • DevOps161
  • Web122
  • Finance36
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai © 2026
    1. Home
    2. Tools
    3. EvalScope
    EvalScope icon

    EvalScope

    LLM Evaluations

    Open-source framework for evaluating LLMs, VLMs, agents and AIGC models and stress-testing model serving performance.

    Visit Website

    At a Glance

    Pricing
    Open Source

    EvalScope core framework released under the Apache License 2.0; free to use, reproduce, modify and distribute.

    Engagement

    Available On

    Web
    API
    SDK
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    LLM EvaluationsPerformance TestingAI Development Libraries

    Alternatives

    FeatherbenchZeroEvalLM Evaluation Harness
    Developer
    ModelScope CommunityEst. 2022

    Listed Oct 2026

    About EvalScope

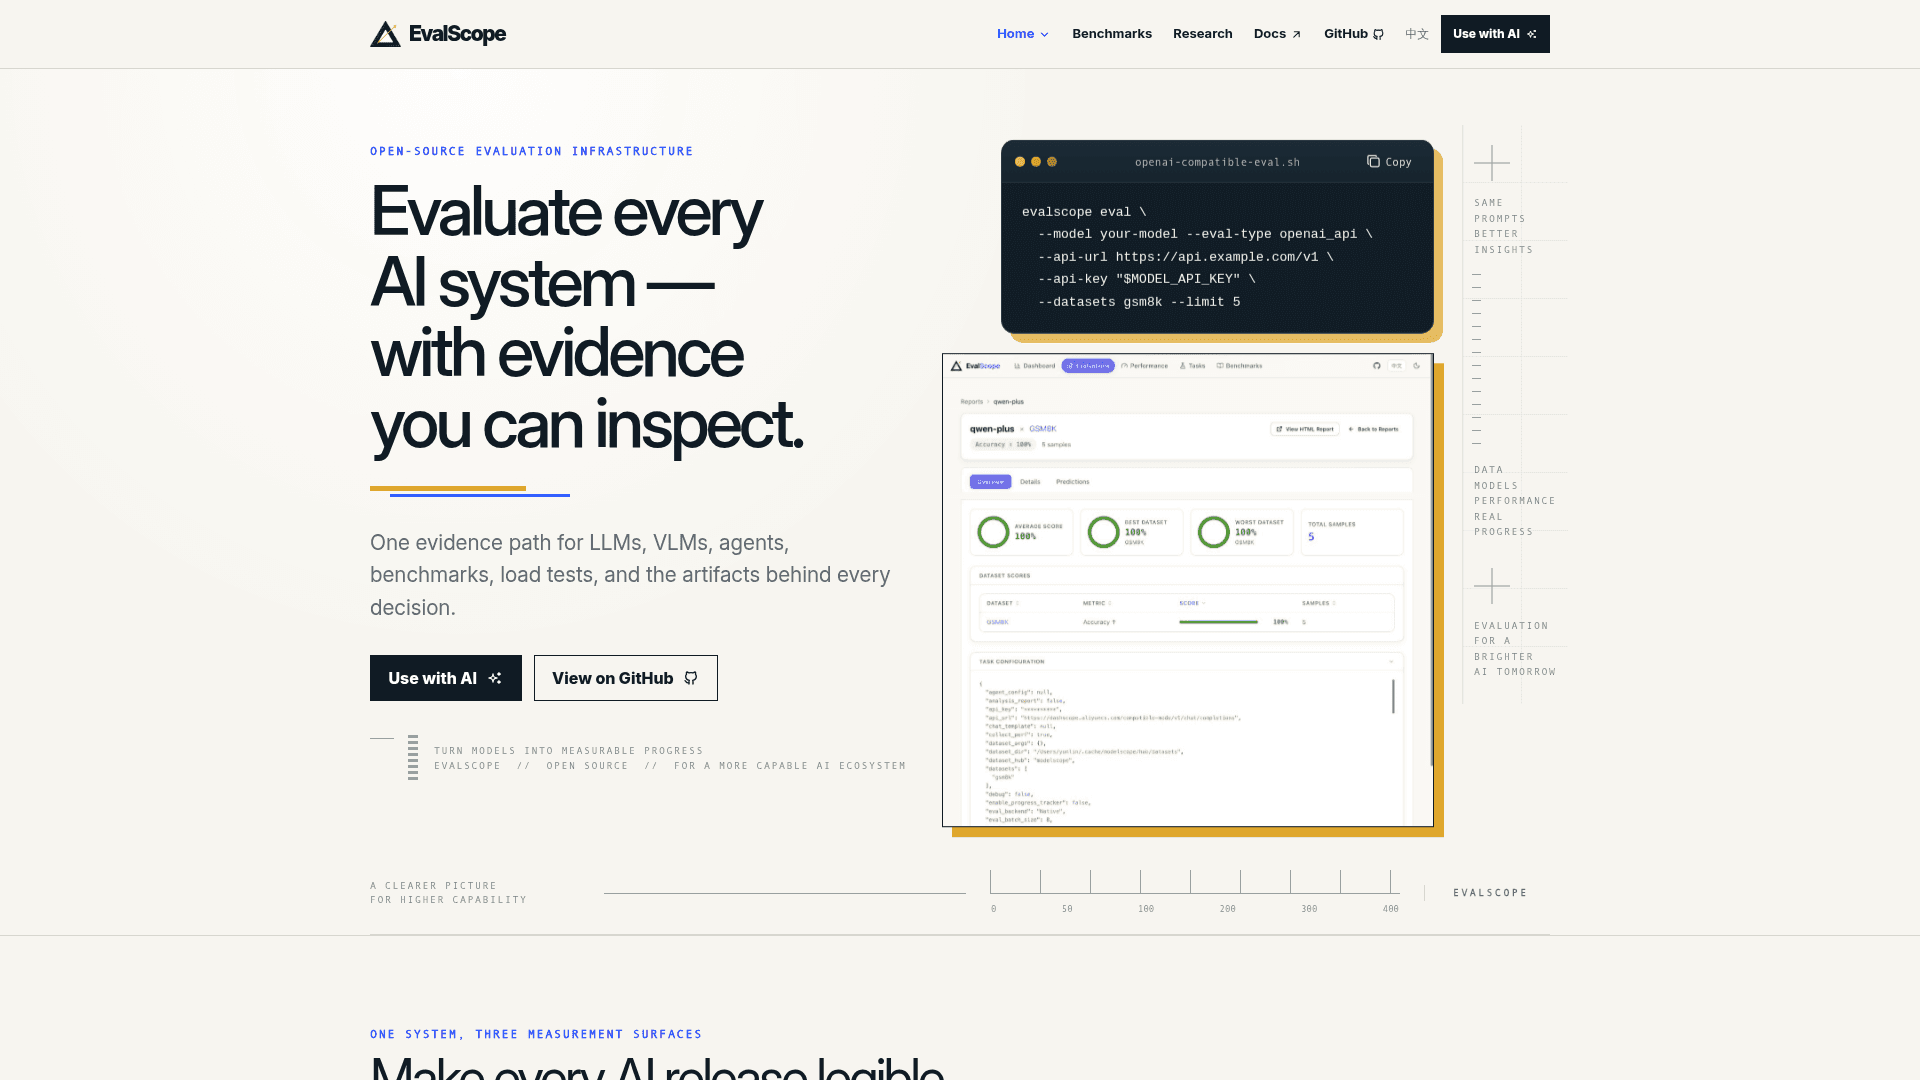
    EvalScope is an open-source evaluation framework from the ModelScope Community. It runs benchmark evaluations of LLMs, VLMs, embedding, reranker and AIGC models, load-tests model services, and produces reports and a web dashboard. The latest release listed on GitHub is v1.12.0.

    What It Is

    EvalScope is a command-line and Python framework for measuring AI systems. A single command such as evalscope eval points at an OpenAI-compatible API or a local model (auto-downloaded from ModelScope), runs selected datasets like GSM8K or ARC, and prints a score table. Results are written to an outputs directory with logs, configs, predictions, reviews and HTML reports.

    Evaluation and Benchmarks

    The project's site says its registry holds 250+ benchmarks across LLM, VLM, agent and AIGC tasks. Beyond the native backend, it can launch OpenCompass, VLMEvalKit and RAG evaluation backends. Other documented modes include Arena Mode, which ranks models through pairwise battles, custom dataset evaluation, and System One Choice evaluation. Metric aggregation such as pass@k is also documented.

    Agent and Harness Evaluation

    Agent evaluation drives benchmarks through a multi-turn agent loop with pluggable strategies, tools such as bash and Python execution, and local or Docker sandbox environments. Each sample records an agent trace of model requests, tool calls and outcomes. An External Agent Bridge can evaluate off-the-shelf agent CLIs like Claude Code and Codex, and MCP servers can be attached as tools.

    Performance Testing and Visualization

    The evalscope perf tool measures concurrency, latency, TTFT, TPOT, RPS, throughput and success rate against a model endpoint. It supports multi-turn stress tests and embedding and reranker services. Results can be sent to wandb, swanlab or ClearML. evalscope service starts a local dashboard for model comparison, report overviews and prediction details.
    EvalScope - 1

    Community Discussions

    Be the first to start a conversation about EvalScope

    Share your experience with EvalScope, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source (Apache-2.0)

    EvalScope core framework released under the Apache License 2.0; free to use, reproduce, modify and distribute.

    • Apache License 2.0
    • LLM, VLM, Embedding, Reranker and AIGC evaluation
    • Inference performance stress testing (TTFT, TPOT)
    • Interactive web dashboard
    • Agent evaluation mode

    Capabilities

    Key Features

    • LLM, VLM, embedding, reranker and AIGC evaluation
    • 250+ benchmark registry
    • Agent evaluation mode with agent traces
    • External agent bridge for Claude Code and Codex
    • MCP server tool support
    • Inference performance stress testing (TTFT, TPOT, RPS, throughput)
    • Web dashboard and HTML reports
    • Arena mode pairwise model battles
    • Custom dataset evaluation
    • Multiple backends: OpenCompass, VLMEvalKit, RAGEval
    • Agent Skill support for natural-language driven evaluation

    Integrations

    OpenAI API
    Anthropic API
    ModelScope
    OpenCompass
    VLMEvalKit
    RAGAS
    MTEB
    Claude Code
    Codex
    Docker
    wandb
    SwanLab
    ClearML
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate EvalScope and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    ModelScope Community

    Founded 2022

    Used by

    Alibaba DAMO Academy / Alibaba Cloud…
    Baichuan and Zhipu (model contributors…
    User-contributed models and application…
    Read more about ModelScope Community
    WebsiteGitHub
    1 tool in directory

    Similar Tools

    Featherbench icon

    Featherbench

    A single-file Python harness for building private LLM benchmarks from JSON tasks and comparing models on pass rate, cost and latency via OpenRouter.

    ZeroEval icon

    ZeroEval

    Open-source evaluation framework for testing large language models with zero-shot prompting on reasoning and coding tasks.

    LM Evaluation Harness icon

    LM Evaluation Harness

    Open-source framework from EleutherAI for few-shot evaluation of language models across many academic benchmarks.

    Browse all tools

    Related Topics

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    177 tools

    Performance Testing

    AI-enhanced tools for load, stress, and endurance testing that analyze application performance under various conditions with predictive insights and optimization recommendations.

    7 tools

    AI Development Libraries

    Programming libraries and frameworks that provide machine learning capabilities, model integration, and AI functionality for developers.

    412 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions