EveryDev.ai
Subscribe
Home
Tools

4,506+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents3274
  • Coding2275
  • Infrastructure1000
  • Projects696
  • Marketing636
  • Research587
  • MCP532
  • Design508
  • Analytics506
  • Testing394
  • Security376
  • Data327
  • Integration244
  • Prompts244
  • Communication235
  • Extensions217
  • Voice193
  • Learning190
  • Commerce170
  • DevOps153
  • Web103
  • Finance36
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai © 2026
    1. Home
    2. Tools
    3. Featherbench
    Featherbench icon

    Featherbench

    LLM Evaluations

    A single-file Python harness for building private LLM benchmarks from JSON tasks and comparing models on pass rate, cost and latency via OpenRouter.

    Visit Website

    At a Glance

    Pricing
    Open Source

    Featherbench is a single-file harness for building your own LLM benchmarks, released under the MIT License. Model usage via OpenRouter is an external cost.

    Engagement

    Available On

    Windows
    macOS
    Linux
    API
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    LLM EvaluationsPerformance TestingAI Development Libraries

    Alternatives

    SubtextLamBenchKillSwitch
    Developer
    Ed YauWhat's better than a data, AI, software sandwich with some a…

    Listed Oct 2026

    About Featherbench

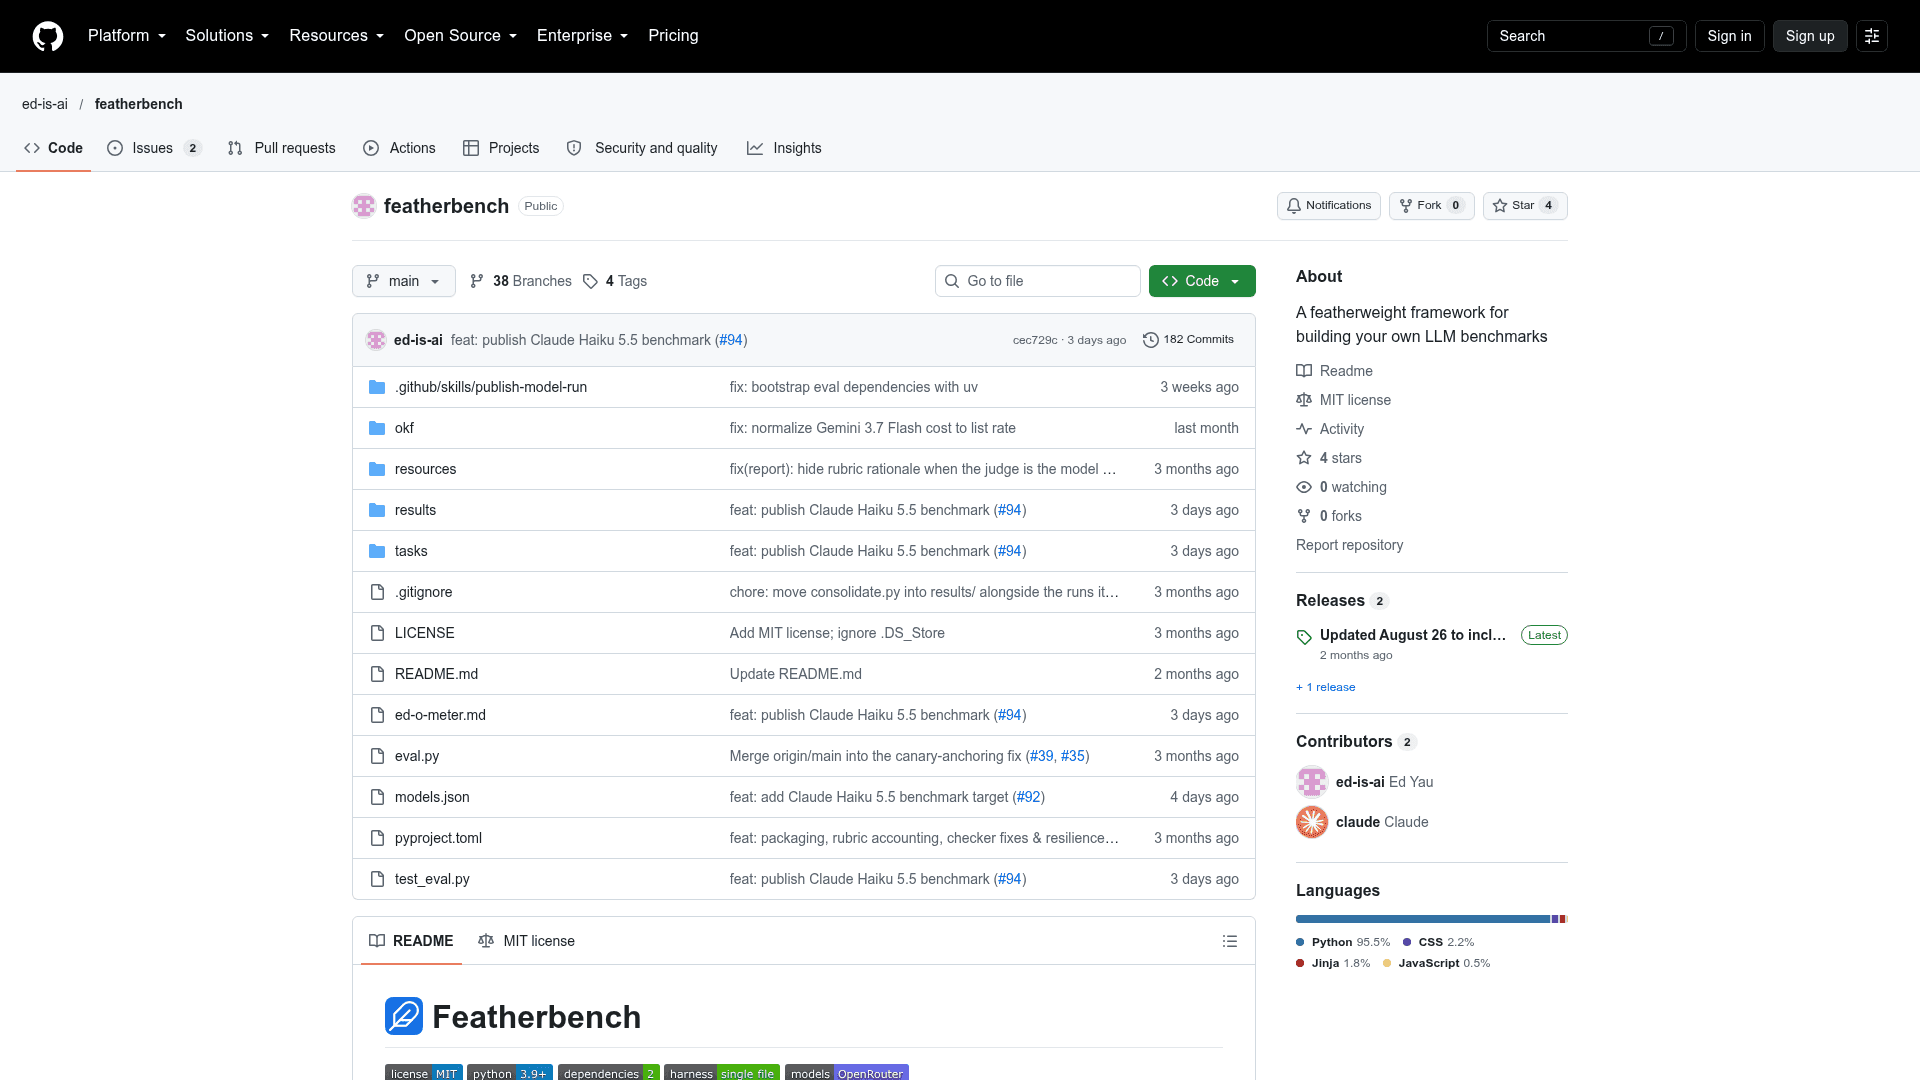
    Featherbench is an open-source, single-file Python harness for creating your own LLM benchmarks from real-world tasks. Tasks are small JSON files, and every selected model is run through one shared scaffold via OpenRouter, so pass rate, cost and latency can be compared directly. It is published under the MIT license and developed by Reinvently, according to the README.

    What It Is

    Featherbench is a framework for teams that want a private task set that models have not seen, rather than relying on public leaderboards. The core harness, eval.py, uses two dependencies (openai as the OpenRouter client, and jinja2 for the HTML report). The README positions it as a lightweight, auditable alternative to heavier platforms such as Inspect AI, promptfoo and Braintrust.

    How a Benchmark Run Works

    You write tasks as JSON files containing a prompt, an optional checker, optional tools and an optional rubric. Checkers include python_tests, regex, contains, not_contains, all, tool_called and tool_not_called. An optional LLM rubric, scored blind by one or more judge models, adds quality scoring on top of the pass/fail floor.

    Models are defined in models.json with an OpenRouter slug, provider routing pins, sampling settings and reasoning effort. A single OPENROUTER_API_KEY covers all of them. Cost is taken from OpenRouter's per-response usage data.

    Outputs

    Each run writes a timestamped JSONL file with per-trial records, a Markdown summary and a self-contained HTML review page. The summary reports pass rate with 95% Wilson confidence intervals, median latency, tokens, cost per model and a per-task grid. A judge-bias matrix is included for rubric tasks. The repo also ships a leaderboard file and a machine-readable summary.json with an Open Knowledge Format bundle.

    Safety and Setup

    It requires Python 3.9+. Tasks using the python_tests checker execute model-generated code in a subprocess with a stripped environment and a timeout, but without filesystem or network isolation. The README recommends running on a sandboxed machine, for example with nono.

    Current Status

    The latest listed release is V1.3, published 2026-08-22.
    Featherbench - 1

    Community Discussions

    Be the first to start a conversation about Featherbench

    Share your experience with Featherbench, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source (MIT)

    Featherbench is a single-file harness for building your own LLM benchmarks, released under the MIT License. Model usage via OpenRouter is an external cost.

    • MIT licensed core harness (eval.py)
    • Single-file Python harness with two dependencies
    • Tasks defined as JSON files
    • JSONL, Markdown summary and HTML review page outputs
    • Model API costs via OpenRouter are paid separately to the provider (external cost)

    Capabilities

    Key Features

    • Single-file Python harness
    • Tasks defined as JSON files
    • Deterministic checkers (python_tests, regex, contains, not_contains, tool_called)
    • Optional cross-judged LLM rubric scoring
    • Pass rate with 95% Wilson confidence intervals
    • Cost and latency tracking per model
    • JSONL, Markdown and HTML report outputs
    • Routing-pinned model catalog via OpenRouter
    • Hard refusal handling per task
    • Tool-use checks for function-calling tasks
    • Concurrent trial execution
    • Unit test suite with mocked providers

    Integrations

    OpenRouter
    OpenAI Python client
    Jinja2
    nono
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate Featherbench and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    Ed Yau

    What's better than a data, AI, software sandwich with some agentic AI hot sauce? Personal space for building stuff in public. No customer work on show here

    Read more about Ed Yau
    GitHubLinkedIn
    1 tool in directory

    Similar Tools

    Subtext icon

    Subtext

    A real-time instrument for observing the internal verbal workspace of a language model as it reads, reasons, and generates text using the Jacobian lens method.

    LamBench icon

    LamBench

    A benchmark of 120 pure lambda calculus programming problems for evaluating how well AI models can implement algorithms using lambda encodings.

    KillSwitch icon

    KillSwitch

    An esoteric programming language designed to be impossible for LLMs and coding agents to generate or modify, with LLM benchmarks to measure model performance.

    Browse all tools

    Related Topics

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    152 tools

    Performance Testing

    AI-enhanced tools for load, stress, and endurance testing that analyze application performance under various conditions with predictive insights and optimization recommendations.

    5 tools

    AI Development Libraries

    Programming libraries and frameworks that provide machine learning capabilities, model integration, and AI functionality for developers.

    362 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions