EveryDev.ai
Subscribe
Home
Tools

5,681+ AI tools

  • Featured
  • Gems
  • Trending
  • New
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2962
  • Coding2238
  • Infrastructure1060
  • Projects817
  • MCP790
  • Research740
  • Analytics561
  • Marketing527
  • Design485
  • Testing473
  • Data442
  • Security408
  • Integration288
  • Communication284
  • Prompts282
  • Extensions238
  • Voice210
  • DevOps189
  • Commerce183
  • Web128
  • Learning122
  • Finance44
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. harness-evals
    harness-evals icon

    harness-evals

    Performance Metrics
    Featured

    Open-source benchmark comparing AI agent harnesses on the same frontier models by pass rate, cost per solved task, and time.

    Visit Website

    At a Glance

    Pricing
    Open Source

    Open source harness evals repository released under the MIT License; free to use, copy, modify and distribute.

    Engagement

    Available On

    API
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    Performance MetricsLLM EvaluationsAgent Harness

    Alternatives

    Claw-Evalagent-eval (is-it-agentic-enough)HarnessEval-W
    Developer
    Garry TanSan Francisco, CAEst. 2005$10.25M raised

    Listed Nov 2026

    About harness-evals

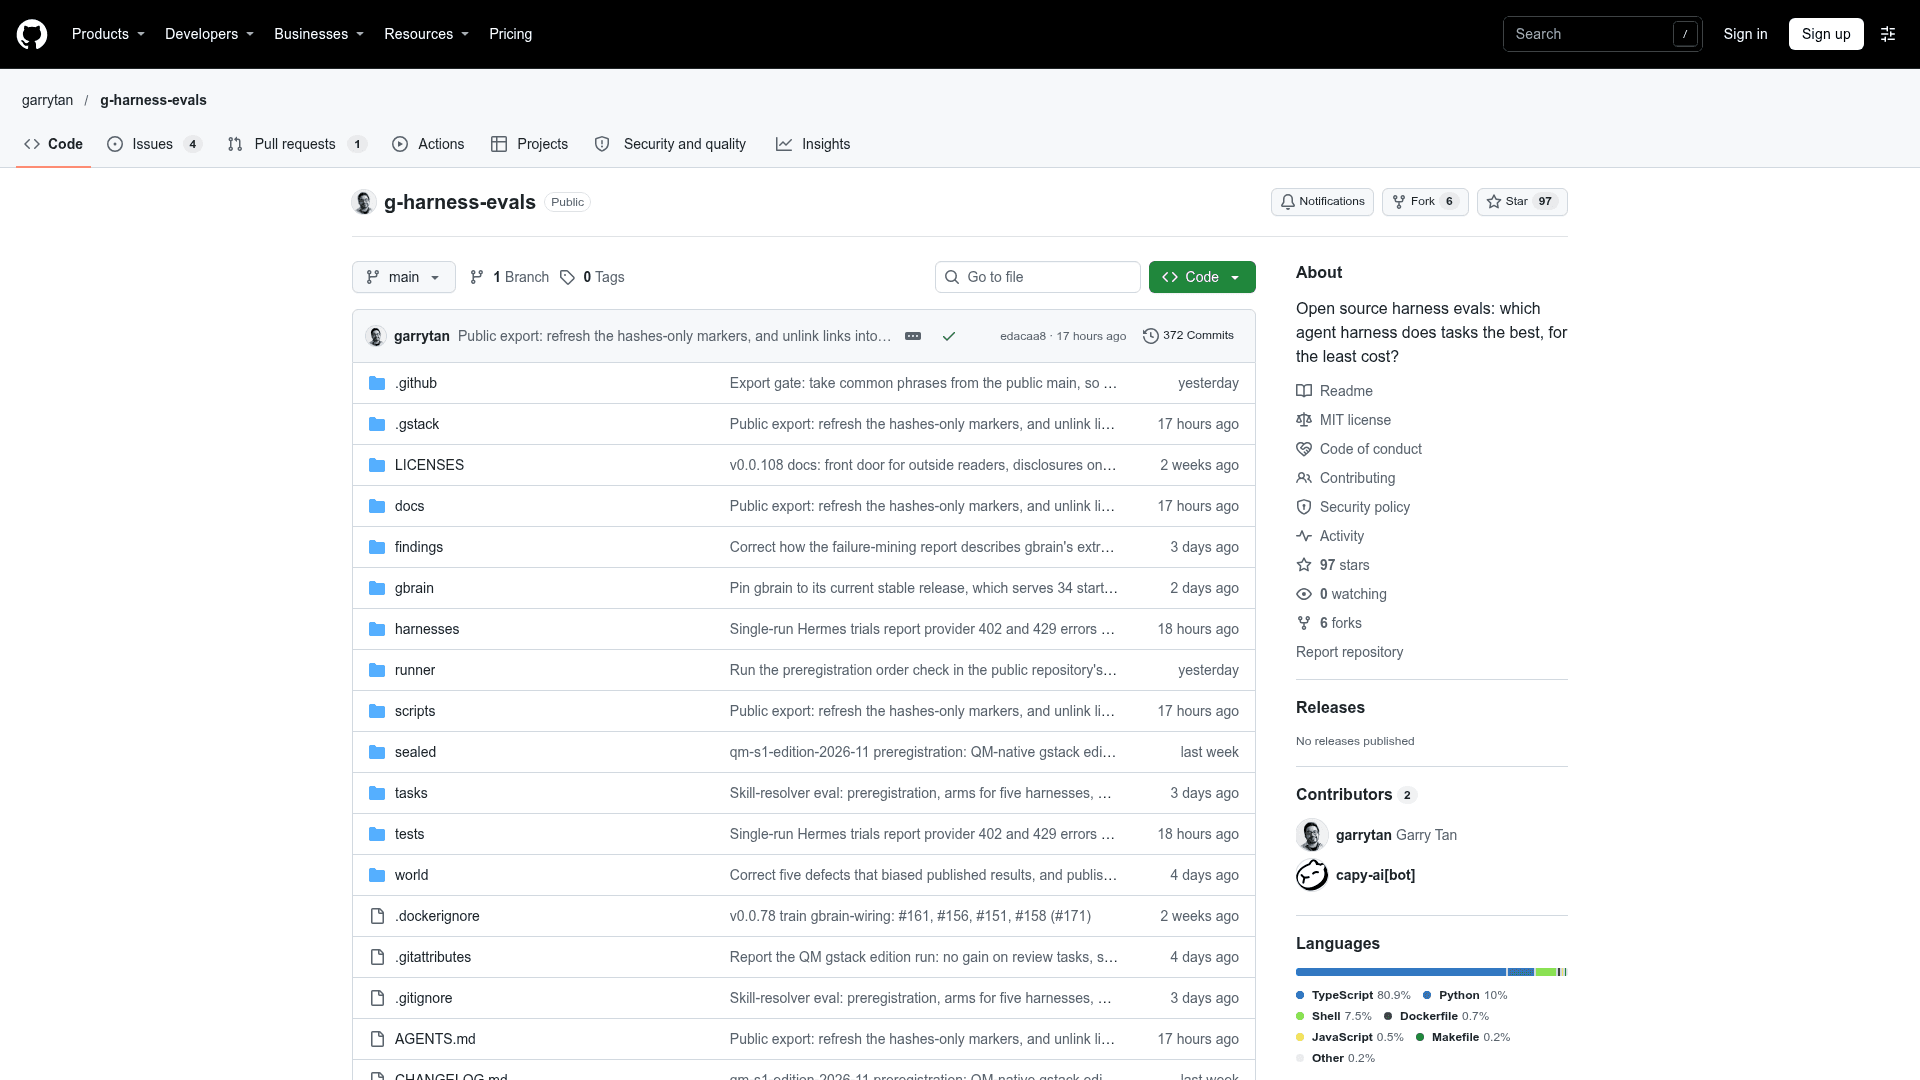
    harness-evals is an open-source evaluation repository run by Garry Tan that compares AI agent harnesses (the system prompt, tools and memory wrapped around a model) while holding the model and tasks constant. It measures how often each harness solves tasks, what each solved task costs, and how long each try takes.

    What It Is

    The repository publishes benchmark results for harnesses such as Claude Code, Codex, OpenClaw, Hermes Agent, Pi and QM. Tests run on Claude Opus 5.5 and GPT-6.1 Sol, using 52 public Terminal-Bench 2.1 coding tasks and 20 multi-user tasks in which the agent acts as a simulated company's chat bot. Rankings are by cost per solved task, with 95% ranges, pass rates and median time per try.

    What the Results Cover

    The README reports that harnesses differed more on cost than on pass rate, and recommends comparing on cost per solved task using your own work. Separate findings examine where must-follow rules are best placed (system prompt or per-turn hook), the cost breakdown of different harnesses, prompt cuts, and shared-brain access rules for gbrain. It also tests gstack skills, reporting that Opus 5.5 read them but did not follow their steps. The README notes these are early results on public tasks and pinned harness versions.

    Running and Verifying It

    The keyless steps call no model and need no API key, only Bun and git. Users clone the repository, install dependencies, rebuild the scoreboard from committed results and check it matches, and recompute the multi-user tables from saved tries. Docs describe replicating a finding with your own key under a spending cap. The README includes disclosures about Garry Tan's connections to several of the tested projects.
    harness-evals - 1

    Community Discussions

    Be the first to start a conversation about harness-evals

    Share your experience with harness-evals, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source (MIT)

    Open source harness evals repository released under the MIT License; free to use, copy, modify and distribute.

    • MIT License
    • Open source harness evals benchmarking agent harnesses on pass rate, cost per solved task and time
    • Model/inference costs for running evals are external

    Capabilities

    Key Features

    • Compares agent harnesses on the same model and tasks
    • Reports pass rate, cost per solved task, and median time per try with 95% ranges
    • 52 Terminal-Bench 2.1 coding tasks and 20 multi-user tasks
    • Findings on rule placement, prompt cuts, and gbrain access rules
    • Published corrections and reproducible scoreboard
    • Keyless scripts to rebuild scoreboard and recompute run summaries

    Integrations

    Claude Code
    Codex
    OpenClaw
    Hermes Agent
    Pi
    QM
    gstack
    gbrain
    Terminal-Bench 2.1
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate harness-evals and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    Garry Tan

    President and CEO of Y Combinator. Co-founder of Initialized Capital and Posterous. Former designer and engineering manager at Palantir. Stanford BS in Computer Systems Engineering.

    Founded 2005
    San Francisco, CA
    $10.25M raised
    85 employees

    Used by

    Stripe
    Airbnb
    Coinbase
    DoorDash
    +6 more
    Read more about Garry Tan
    WebsiteGitHubLinkedInX / Twitter
    3 tools in directory

    Similar Tools

    Claw-Eval icon

    Claw-Eval

    Open-source evaluation harness and benchmark for testing LLMs as autonomous agents on 300 human-verified tasks.

    agent-eval (is-it-agentic-enough) icon

    agent-eval (is-it-agentic-enough)

    Benchmarks how coding agents use a library across revisions and models, producing a static HTML report publishable as a Hugging Face Space.

    HarnessEval-W icon

    HarnessEval-W

    An agentified benchmark and evaluation pipeline that scores world-model video generation with inspectable evidence trees.

    Browse all tools

    Related Topics

    Performance Metrics

    Specialized tools for measuring, evaluating, and optimizing AI model performance across accuracy, speed, resource utilization, and other critical parameters.

    102 tools

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    242 tools

    Agent Harness

    Infrastructure, orchestrators, and task runners that wrap around LLM coding agents — covering session management, context delivery, worktree isolation, architecture enforcement, and issue-to-PR pipelines.

    444 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions