EveryDev.ai
Subscribe
Home
Tools

4,741+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents3426
  • Coding2391
  • Infrastructure1055
  • Projects732
  • Marketing662
  • Research612
  • MCP593
  • Analytics538
  • Design533
  • Testing420
  • Security410
  • Data358
  • Prompts260
  • Integration256
  • Communication250
  • Extensions222
  • Voice201
  • Learning193
  • Commerce173
  • DevOps161
  • Web122
  • Finance36
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai © 2026
    1. Home
    2. Tools
    3. LMMs-Eval
    LMMs-Eval icon

    LMMs-Eval

    LLM Evaluations
    Featured

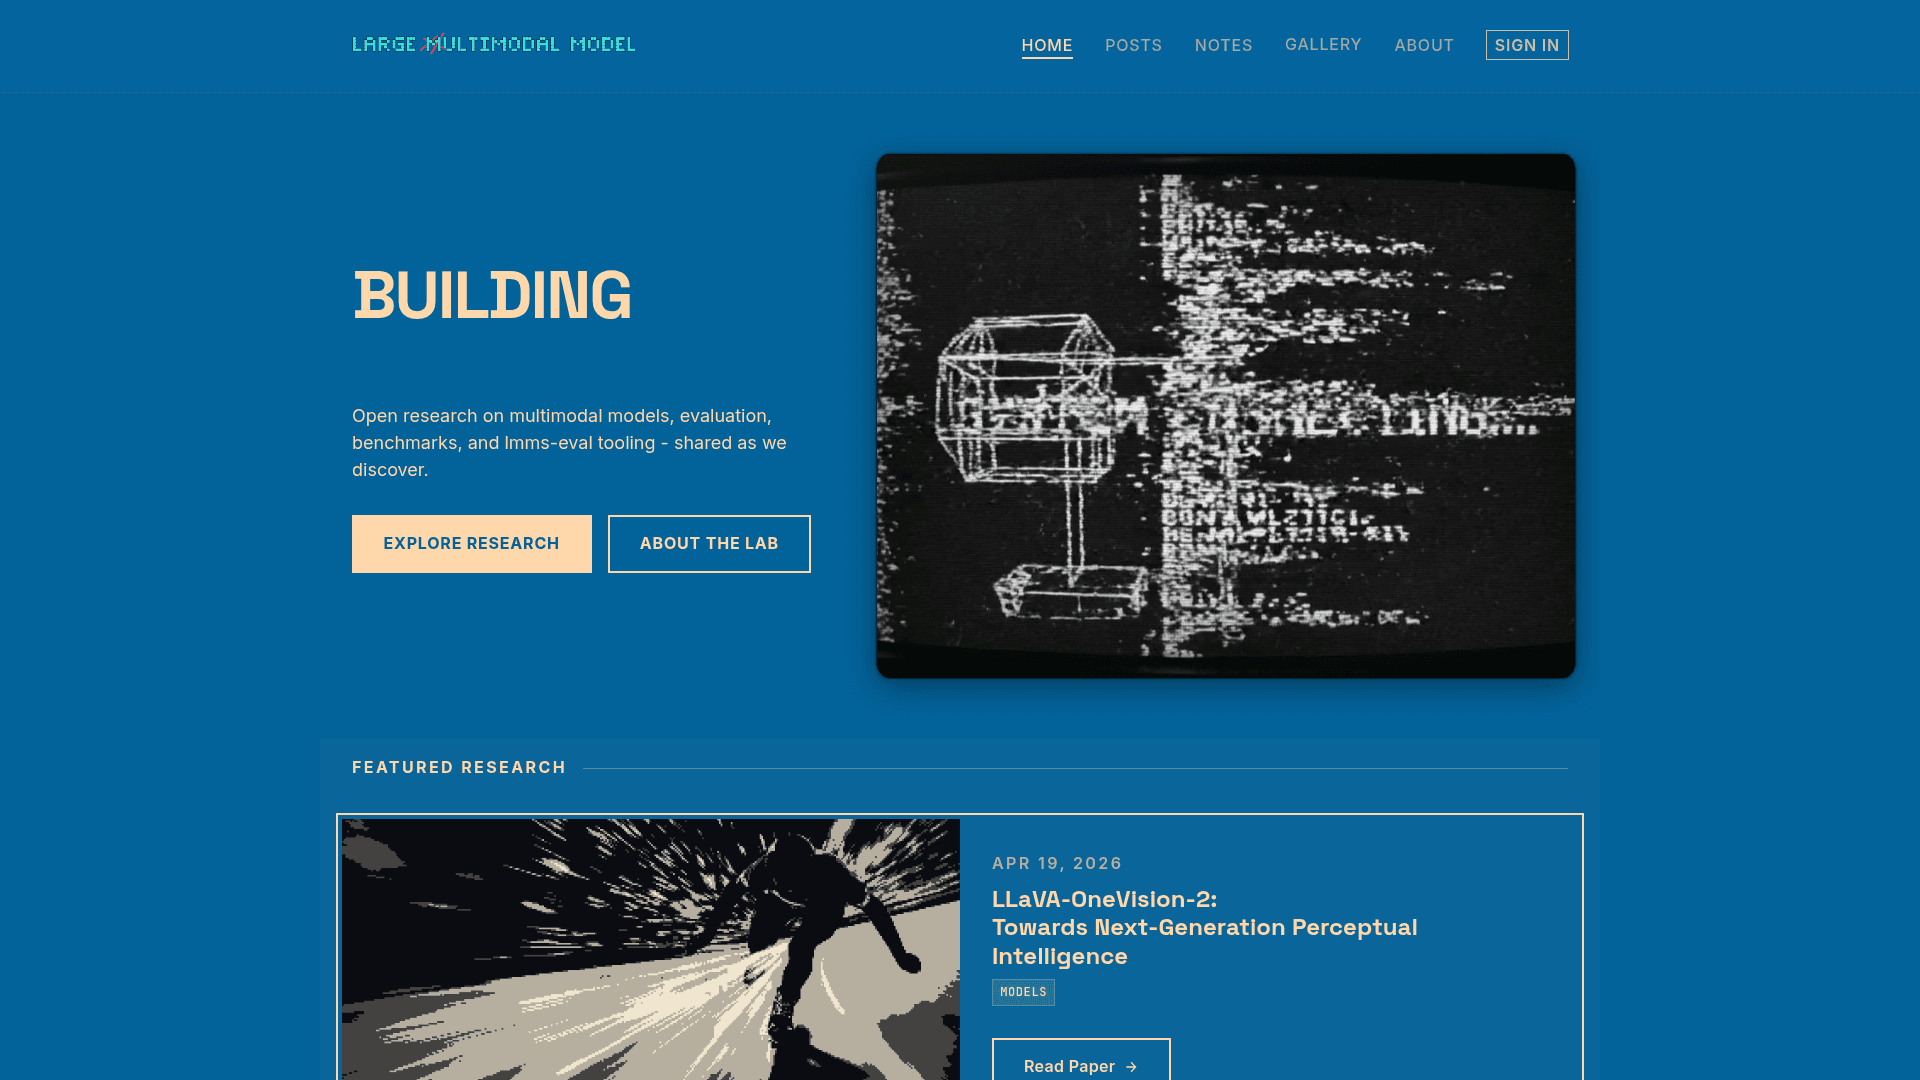
    Unified open-source evaluation toolkit for multimodal models across text, image, video, and audio tasks.

    Visit Website

    At a Glance

    Pricing
    Open Source

    Self-hosted multimodal evaluation toolkit under MIT (main pipeline) and Apache 2.0 (added models and tasks code) licenses.

    Engagement

    Available On

    CLI
    Web
    API
    SDK

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    LLM EvaluationsAI Development LibrariesPerformance Metrics

    Alternatives

    OpenCompassMTEBNeedle In A Haystack
    Developer
    LMMs-LabEst. 2024

    Listed Oct 2026

    About LMMs-Eval

    LMMs-Eval is an evaluation toolkit from the non-profit research organization LMMs-Lab. It runs benchmarks for large multimodal models across text, image, video, and audio tasks through a single pipeline. The latest release listed on GitHub is v0.7.3.

    What It Is

    LMMs-Eval is a Python benchmarking framework forked from EleutherAI's lm-evaluation-harness and adapted for multimodal inputs. Users pick a model and one or more tasks, then run evaluations from the command line, a web UI, or an HTTP server. The README states three principles: reproducible, efficient, and trustworthy results, including confidence intervals, clustered standard errors, and paired comparisons.

    Running Evaluations

    The README documents a quickstart that installs the package with uv and evaluates a model such as Qwen2.5-VL on a benchmark like MME. Backends include vLLM, SGLang, Hugging Face model wrappers, and any OpenAI-compatible endpoint. The README says it covers 100+ tasks and 30+ model families, including MMMU, MME, MMBench, MathVista, and VideoMME. Environment variables such as OPENAI_API_KEY and HF_TOKEN are needed for some tasks.

    Extending It

    Chat models are the recommended interface, using structured messages with roles and interleaved text, image, video, and audio content. Legacy simple models use separate visual and text functions. New benchmarks are added through a YAML task configuration plus a doc_to_messages function.

    Web UI and Eval Server

    An optional web UI offers model and task selection, a live command preview, streaming output, and a log viewer. A separate HTTP evaluation server accepts jobs asynchronously via sync and async Python clients, so evaluations can run on dedicated GPU nodes while training continues. The README warns that the server is for trusted environments only.

    Recent Releases

    The README lists v0.7 (Feb 2026) as adding 25+ tasks, agentic task evaluation, a faster video I/O path with TorchCodec, safety baselines, and efficiency metrics. v0.6 introduced the standalone eval server and statistical results such as confidence intervals and paired t-tests.
    LMMs-Eval - 1

    Community Discussions

    Be the first to start a conversation about LMMs-Eval

    Share your experience with LMMs-Eval, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    Self-hosted multimodal evaluation toolkit under MIT (main pipeline) and Apache 2.0 (added models and tasks code) licenses.

    • Main pipeline code under MIT License
    • Multimodal models and tasks code (lmms_eval/tasks and lmms_eval/models) under Apache License 2.0
    • 100+ tasks
    • 30+ models

    Capabilities

    Key Features

    • Unified evaluation across text, image, video, and audio tasks
    • 100+ benchmark tasks
    • 30+ supported model families
    • vLLM, SGLang, and OpenAI-compatible backends
    • Chat-style multimodal message protocol
    • YAML-based custom task configuration
    • Confidence intervals and paired statistical comparisons
    • Optional web UI for configuring and running evaluations
    • Asynchronous HTTP evaluation server with sync and async clients
    • Agentic task evaluation
    • Response caching

    Integrations

    vLLM
    SGLang
    OpenAI API
    Hugging Face
    Qwen2.5-VL
    Qwen3-VL
    LLaVA-OneVision
    Weights & Biases
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate LMMs-Eval and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    LMMs-Lab

    LMMs-Lab is a non-profit, research-oriented organization of researchers passionate about developing multimodal intelligence. It was founded by Bo Li with his friends and is supported by Prof. Ziwei Liu. The lab publishes open research on multimodal models, evaluation, and benchmarks, and maintains projects such as LMMs-Eval and LMMs-Engine.

    Founded 2024
    Read more about LMMs-Lab
    WebsiteGitHubX / Twitter
    1 tool in directory

    Similar Tools

    OpenCompass icon

    OpenCompass

    Open-source platform for evaluating large language and multimodal models across 100+ datasets.

    MTEB icon

    MTEB

    Python toolbox for benchmarking and evaluating embedding models and retrieval systems across tasks, languages, and modalities.

    Needle In A Haystack icon

    Needle In A Haystack

    A CLI tool that pressure-tests LLM long-context retrieval by sweeping context length and needle depth combinations to measure model accuracy.

    Browse all tools

    Related Topics

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    177 tools

    AI Development Libraries

    Programming libraries and frameworks that provide machine learning capabilities, model integration, and AI functionality for developers.

    412 tools

    Performance Metrics

    Specialized tools for measuring, evaluating, and optimizing AI model performance across accuracy, speed, resource utilization, and other critical parameters.

    80 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions