EveryDev.ai
Subscribe
Home
Tools

4,536+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents3274
  • Coding2275
  • Infrastructure1000
  • Projects696
  • Marketing636
  • Research587
  • MCP532
  • Design508
  • Analytics506
  • Testing394
  • Security376
  • Data327
  • Integration244
  • Prompts244
  • Communication235
  • Extensions217
  • Voice193
  • Learning190
  • Commerce170
  • DevOps153
  • Web103
  • Finance36
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai © 2026
    1. Home
    2. Tools
    3. MTEB
    MTEB icon

    MTEB

    LLM Evaluations

    Python toolbox for benchmarking and evaluating embedding models and retrieval systems across tasks, languages, and modalities.

    Visit Website

    At a Glance

    Pricing
    Open Source

    MTEB Python package for evaluating embeddings, licensed under Apache License 2.0.

    Engagement

    Available On

    API
    SDK
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    LLM EvaluationsAI Development LibrariesPerformance Metrics

    Alternatives

    Artificial AnalysisBridgeBenchDesign Arena
    Developer
    Massive Text Embedding BenchmarkEst. 2022

    Listed Oct 2026

    About MTEB

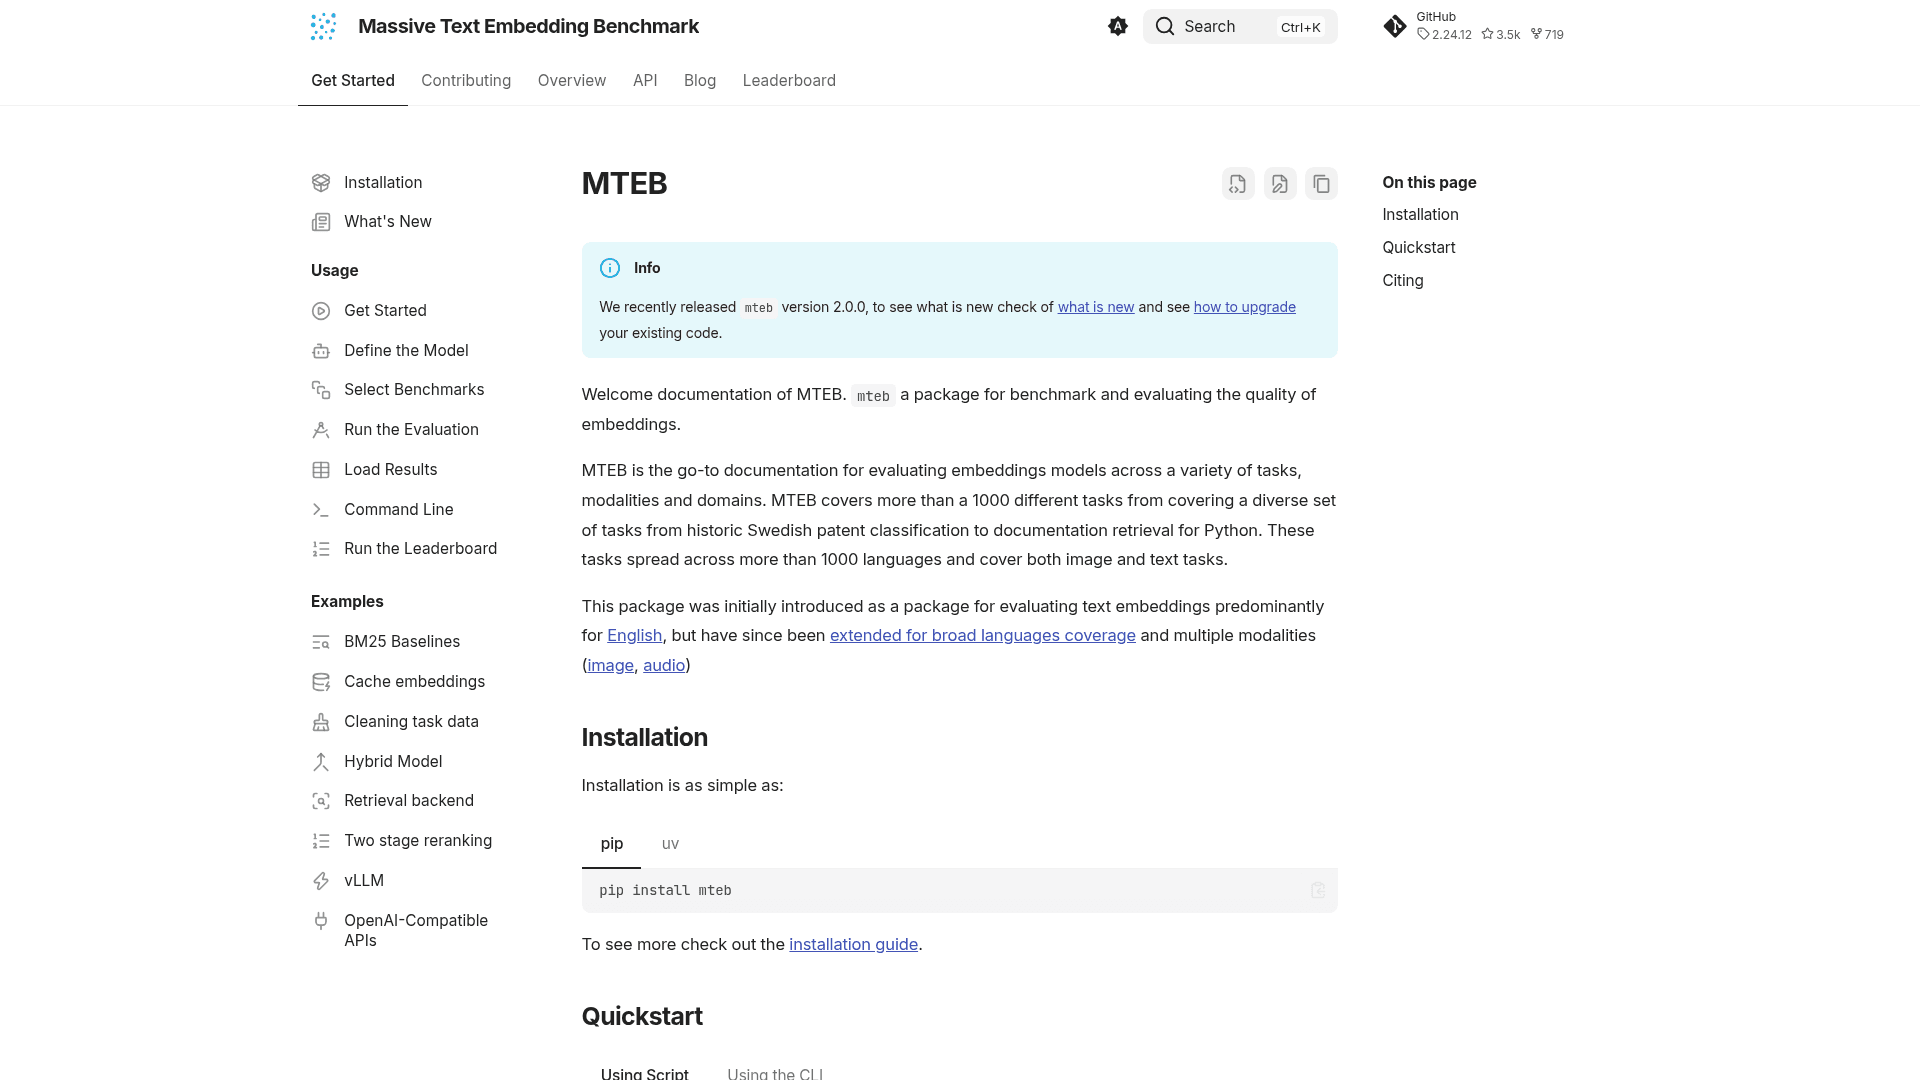
    MTEB (Massive Text Embedding Benchmark) is an open-source Python package from the embeddings-benchmark organization for evaluating the quality of embeddings. It lets users pick a model, select tasks or benchmarks, and run evaluations from a script or the command line. The documentation describes more than 1000 tasks across more than 1000 languages, covering text and image tasks, with audio support also referenced.

    What It Is

    MTEB is an evaluation toolkit for embedding models and retrieval systems. It started as a package for evaluating text embeddings, predominantly in English, and was later extended to broader language coverage and to multiple modalities, including image and audio. It is installed with pip or uv and released under the Apache 2.0 license.

    How an Evaluation Works

    The workflow has three steps: load a model with mteb.get_model, choose tasks with mteb.get_tasks or a benchmark with mteb.get_benchmark, and call mteb.evaluate. If a model is not implemented in MTEB, it falls back to a SentenceTransformer. The same run is available from the CLI with mteb run, which takes a model, task names, and an output folder. Benchmark objects expose citation information and can export their task list as a LaTeX table.

    Ecosystem and Extensions

    The docs include guides for loading existing results, caching embeddings, BM25 baselines, hybrid models, retrieval backends, two-stage reranking, and vLLM and OpenAI-compatible API wrappers. Task categories include retrieval, classification, clustering, semantic similarity, and pair classification. Contributors can add models, tasks, benchmarks, and submit results, and a leaderboard can be run locally or viewed online.
    MTEB - 1

    Community Discussions

    Be the first to start a conversation about MTEB

    Share your experience with MTEB, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    MTEB Python package for evaluating embeddings, licensed under Apache License 2.0.

    • Apache License 2.0 (OSI-approved)
    • Install via pip install mteb or uv add mteb
    • Python library and CLI (mteb run)
    • Evaluation across text, image and audio embedding tasks

    Capabilities

    Key Features

    • Evaluate embedding models across 1000+ tasks
    • Multilingual coverage across 1000+ languages
    • Text, image, and audio modality support
    • Python API and CLI (mteb run)
    • Benchmark selection with citation and LaTeX task export
    • Load and work with existing model results
    • Result caching and embedding cache
    • BM25 baselines, hybrid models, and two-stage reranking
    • vLLM and OpenAI-compatible API wrappers
    • Local leaderboard and contribution workflows for models, tasks, and benchmarks

    Integrations

    Sentence Transformers
    Hugging Face
    vLLM
    OpenAI-compatible APIs
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate MTEB and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    Massive Text Embedding Benchmark

    Founded 2022
    Read more about Massive Text Embedding Benchmark
    WebsiteGitHub
    1 tool in directory

    Similar Tools

    Artificial Analysis icon

    Artificial Analysis

    Independent AI benchmarking platform that evaluates and compares AI models across intelligence, speed, cost, and capabilities to help users choose the best model and provider for their use case.

    BridgeBench icon

    BridgeBench

    BridgeBench ranks AI coding models across UI generation, security, refactoring, hallucination, debugging, and speed benchmarks.

    Design Arena icon

    Design Arena

    A crowdsourced benchmark platform that pits top AI models against each other on design tasks and lets users vote to power live leaderboards.

    Browse all tools

    Related Topics

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    156 tools

    AI Development Libraries

    Programming libraries and frameworks that provide machine learning capabilities, model integration, and AI functionality for developers.

    373 tools

    Performance Metrics

    Specialized tools for measuring, evaluating, and optimizing AI model performance across accuracy, speed, resource utilization, and other critical parameters.

    77 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions