
NVIDIA Personal AI Router (PAIR)
Local inference router that distributes independent AI requests across paired computers on the same network.
At a Glance
NVIDIA Personal AI Router (PAIR) core product licensed under Apache License 2.0; free to use, modify and distribute.
Engagement
Available On
Listed Oct 2026
About NVIDIA Personal AI Router (PAIR)
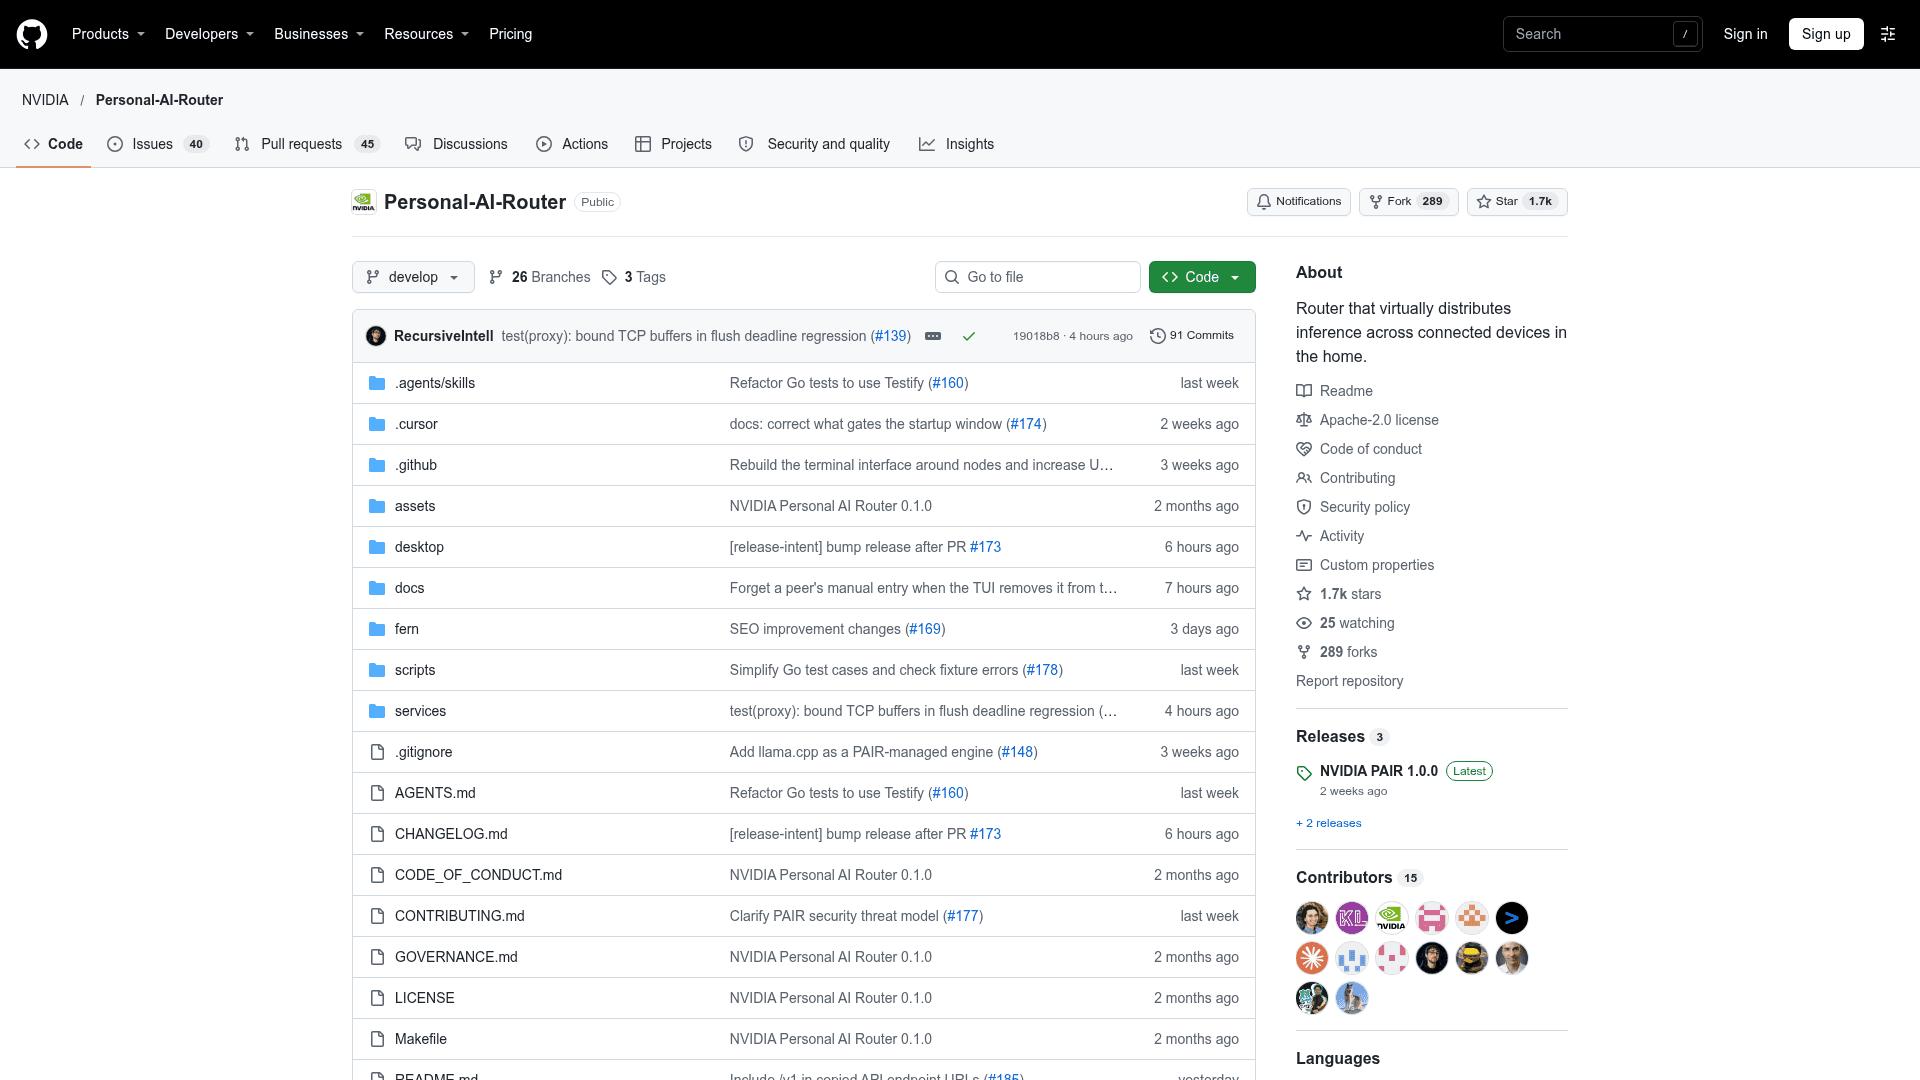
NVIDIA Personal AI Router (PAIR) is an open-source local inference router from NVIDIA for a group of compatible computers on the same network. It discovers participating nodes, manages supported inference engines, and exposes local proxy endpoints compatible with Ollama, OpenAI, and Anthropic Messages API requests. The latest listed release is v0.1.1.
What It Is
PAIR is a desktop application with background services that sits in front of local inference engines (Ollama, LM Studio, and llama.cpp). Each independent request is routed to one eligible node based on engine availability, model availability, and current workload. The README describes it as useful for concurrent local workloads such as multi-agent applications, and says prompts and responses are intended to stay on the local network when every client, model source, engine, and node is local.
PAIR does not pool GPU memory, shard a model across machines, or split an in-flight request between nodes.
How the Workflow Runs
Users install a released build (Windows installer, Linux .deb, or macOS .dmg), open the app, and install an engine from a node's Engine settings. They then add a model, such as a GGUF model from Hugging Face for llama.cpp, and send a request to the local endpoint, for example an OpenAI-style chat completions call on the Ollama default port. The Overview and Jobs views show which node served each request, with live GPU and memory use per node.
To route across machines, a second computer is paired from Settings → Cluster using a six-digit PIN shown on the inviting machine. Windows, Linux, and macOS nodes can be mixed.
Platforms and Interfaces
PAIR runs on Windows 11, Linux, and macOS on x64 and arm64, with Windows on ARM marked experimental. A terminal interface is available for machines without a desktop, and the project can be built from source. Whether an engine and model work on a given machine depends on that engine's own requirements.
Roadmap Direction
The README lists planned work such as vLLM and EXO support, request queuing, KV cache-aware scheduling, and requester-only clients, described as a direction rather than a commitment.
Community Discussions
Be the first to start a conversation about NVIDIA Personal AI Router (PAIR)
Share your experience with NVIDIA Personal AI Router (PAIR), ask questions, or help others learn from your insights.
Pricing
Open Source
NVIDIA Personal AI Router (PAIR) core product licensed under Apache License 2.0; free to use, modify and distribute.
- Licensed under Apache License 2.0
- Local inference router for compatible computers on the same network
- Supports Ollama, LM Studio, and llama.cpp engines
- Windows 11, Linux, and macOS installers
- Inference engines, models, and other software used with PAIR may have separate terms
Capabilities
Key Features
- Automatic discovery and pairing of nodes on the same network via PIN
- Routes independent requests by engine availability, model availability, and workload
- Ollama-compatible, OpenAI-compatible, and Anthropic Messages API proxy endpoints
- Install and manage Ollama, LM Studio, and llama.cpp engines from the app
- Add and download models from the node card
- Live per-node GPU and memory monitoring with a Jobs view
- Built-in test traffic generator
- Terminal interface for headless machines
- Mixed Windows, Linux, and macOS clusters
- Signed installers with in-app update notifications