
Ripple-65B Preview
An Apache 2.0 open-weight 65B dense model from Ricursive Intelligence, tuned for agentic coding, with up to 1M tokens of context and small enough to run on an NVIDIA DGX Spark.
At a Glance
About Ripple-65B Preview
Ripple-65B Preview is an open-weight language model from Ricursive Intelligence, released under the Apache 2.0 license. It is a general-purpose variant of the proprietary model behind the company's AI chip design platform. It is a 65B-parameter dense Transformer, pretrained from scratch on 12 trillion tokens, with up to 1M tokens of context and post-training focused on agentic coding.
What It Is
Ripple-65B Preview is a text-in, text-out model for coding agents, reasoning, and long-context work. The release includes an instruction-tuned model in BF16, an NVFP4 version of the same model for local use, a pretrain-only BF16 base model, and a DFlash2 draft model for speculative decoding. It supports native tool calling, and its training data is mostly English text and code.
The weights can be downloaded from Hugging Face, and the model is served by Together AI, GMI Cloud, OpenRouter, and Fireworks. Ricursive says its 65B size lets it fit on consumer hardware such as the NVIDIA DGX Spark, and it publishes an NVFP4 checkpoint and a Colab notebook to help people run it locally.
Architecture
Ricursive chose a dense Transformer over Mixture-of-Experts to keep training and serving simpler. The model is thin and deep, with a model dimension of 5,120 and 80 layers, and moves from Olmo 3's Llama-like design to a Gemma 3N-like design for stability at scale. It uses extra attention heads, a mix of sliding-window and global attention, gated attention, global NoPE, value residuals, and FFN activation clipping. Ricursive reports 250 tokens per second on two NVIDIA B200 GPUs at batch size 8 before quantization or custom kernels.
Benchmark Claims
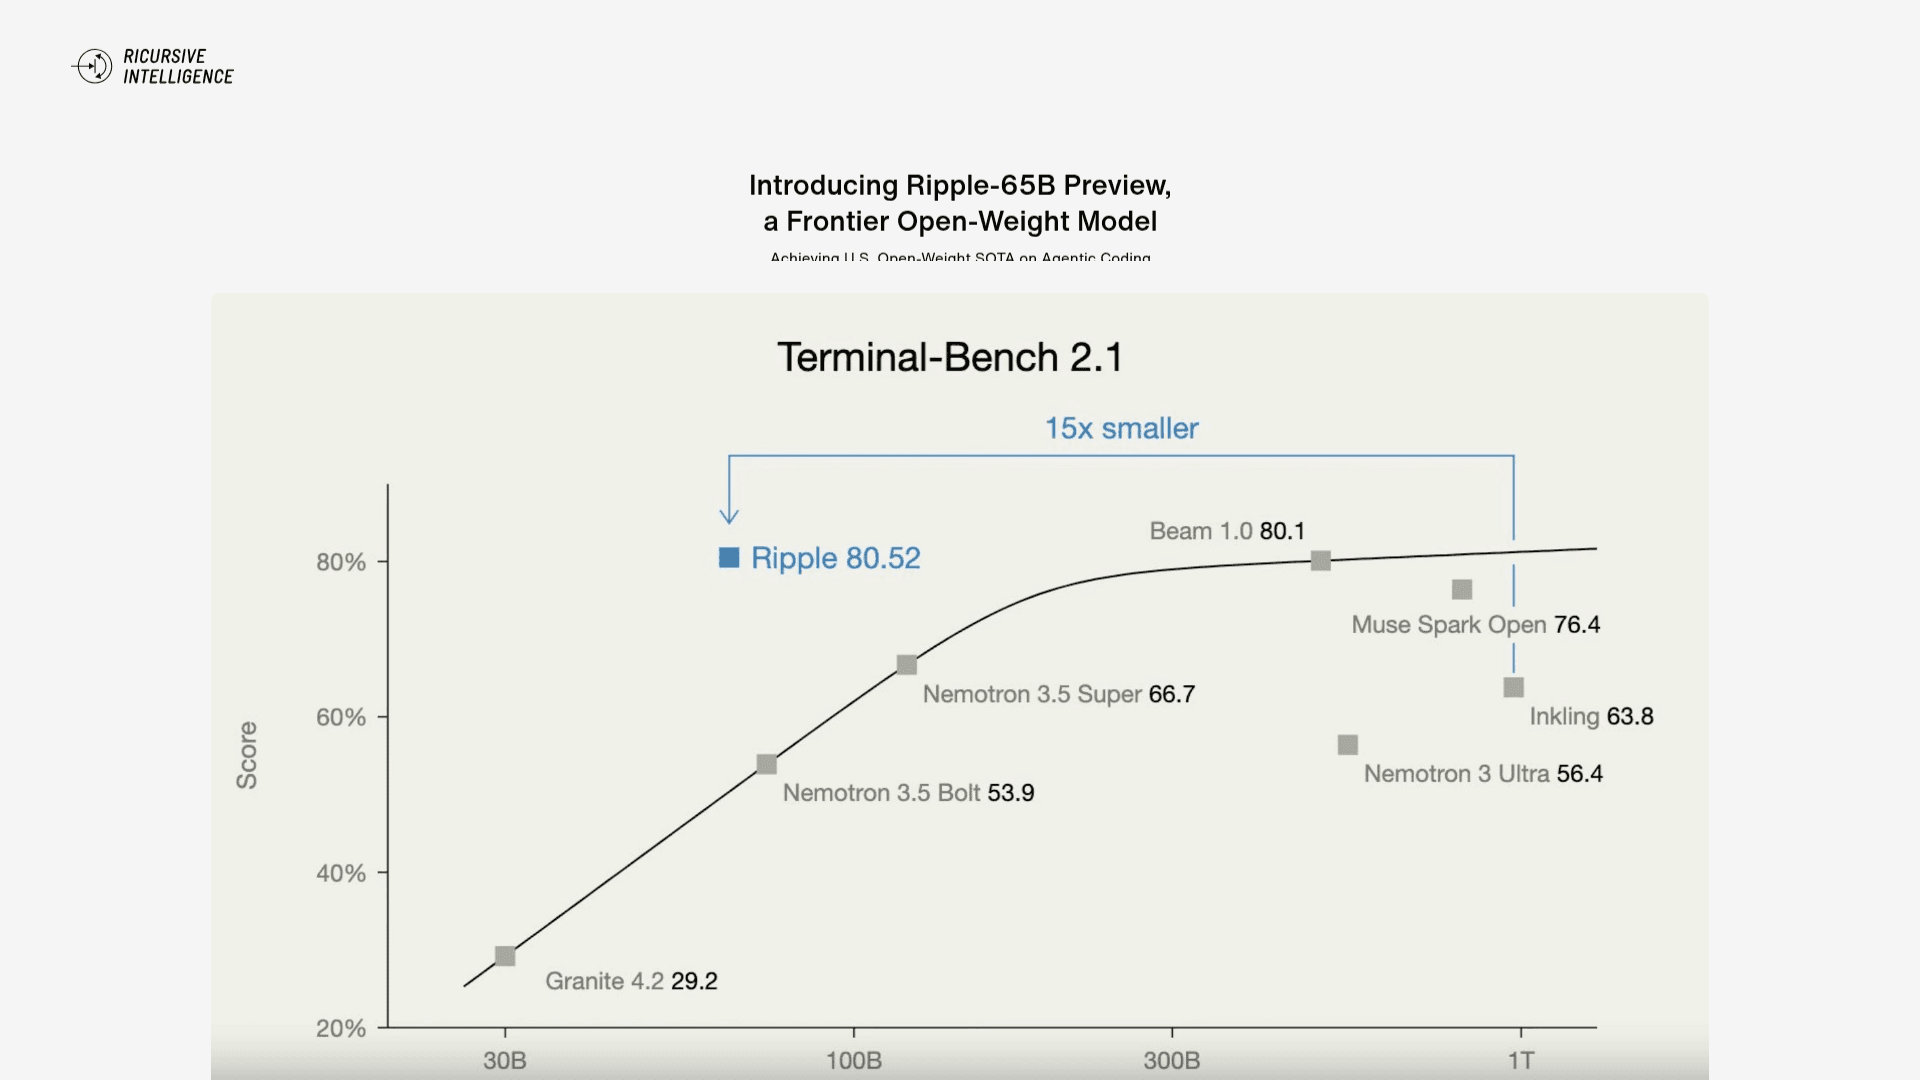
All scores are published by Ricursive for the instruction-tuned model at full precision and maximum effort. It reports 80.52 on Terminal-Bench 2.1, which it calls the U.S. open-weight state of the art, ahead of larger models such as Reflection Beam 501B, Meta Muse Spark Open 816B, Thinking Machines Inkling 975B, and NVIDIA Nemotron 3 Ultra 550B. Other reported results include 79.1 on SWE-bench Pro v2.0 Hard, 76.5 on SWE-bench Verified, 44.3 on DeepSWE 1.1, 85.2 on GPQA Diamond, 90.5 on HMMT February 2026, 71.67 on MCP Atlas, and 75.0 on AA-LCR for long context. Ricursive notes that agentic benchmark scores are hard to reproduce and calls its comparison table a best-effort attempt at fairness; some competitor scores come from its own evaluation setup.
Training Approach
Ricursive says the model was built by a team that grew from one to five people, and puts its full research and development cost from scratch at about one-tenth that of the previous open-weight leader in agentic coding. It reports that its pretraining recipe, which started from Olmo 3's model ladder and added code-heavy data and architecture changes, needs up to 16 times less compute for the same code performance at small scale. Post-training ran through midtraining, long-context training, supervised fine-tuning, long-context fine-tuning, and mixed reinforcement learning on synthetic long-horizon tasks, without bought post-training data. Ricursive says it reached its Terminal-Bench score with 1.4M reinforcement learning rollouts.
Preview Status
Ricursive describes this release as a preview with relatively light post-training focused on agentic coding. Hosted context limits vary by provider: Together AI lists a 128K context window, while OpenRouter and Fireworks list about 1M tokens.
Community Discussions
Be the first to start a conversation about Ripple-65B Preview
Share your experience with Ripple-65B Preview, ask questions, or help others learn from your insights.
Pricing
Open Weights
Download and self-host the model weights from Hugging Face under the Apache 2.0 license, including commercial use.
- Apache 2.0 license
- Instruction-tuned model in BF16 and NVFP4
- Pretrain-only BF16 base model
- DFlash2 draft model for speculative decoding
- Runs locally on hardware such as NVIDIA DGX Spark
Hosted API
Pay-per-token access through third-party providers. Listed rates are $0.20 per 1M input tokens and $0.60 per 1M output tokens on both OpenRouter and Together AI.
- $0.20 per 1M input tokens
- $0.60 per 1M output tokens
- Cached input: $0.05 per 1M on OpenRouter (served by GMI Cloud), $0.02 per 1M on Together AI
- Together AI serverless and dedicated endpoints
- Fireworks on-demand dedicated GPU deployments
- OpenAI-compatible API through OpenRouter
Capabilities
Key Features
- 65B-parameter dense Transformer (no Mixture-of-Experts)
- Pretrained from scratch on 12 trillion tokens
- Up to 1,048,576 tokens of context
- Post-training focused on agentic coding
- Native tool calling
- JSON output through response_format on OpenRouter
- Instruction-tuned BF16 and NVFP4 checkpoints
- Pretrain-only BF16 base model
- DFlash2 draft model for speculative decoding
- Fits on local hardware such as NVIDIA DGX Spark
- Colab notebook for getting started locally
- Apache 2.0 open-weight license
- Thin-and-deep design: 80 layers, model dimension 5,120
- Sliding-window plus global attention with gated attention, global NoPE, and value residuals
- Hosted on Together AI, GMI Cloud, OpenRouter, and Fireworks