
SenseNova-Loop-9B-Preview
Open-source looped multimodal language model for long-context and agentic workflows that accepts text and images and generates text.
At a Glance
SenseNova-Loop-9B-Preview model and repository released under the Apache License 2.0; self-hosted, no-charge license grant.
Engagement
Available On
Alternatives
Listed Nov 2026
About SenseNova-Loop-9B-Preview
SenseNova-Loop-9B-Preview is a multimodal language model published by the OpenSenseNova organization under the Apache 2.0 license. It accepts text and images and generates text, targeting document understanding, coding, and interaction with external tools. The repository documents the architecture, Transformers usage, training commands, and deployment paths.
What It Is
SenseNova-Loop-9B-Preview is an autoregressive multimodal decoder built for long-context and agentic workflows. According to the README, it has about 9B total parameters and about 14.6B inference parameters, with training recipes at sequence lengths up to 262,144 tokens. Weights are distributed through Hugging Face and ModelScope, and the repository provides the documentation around them.
How the Looped Architecture Works
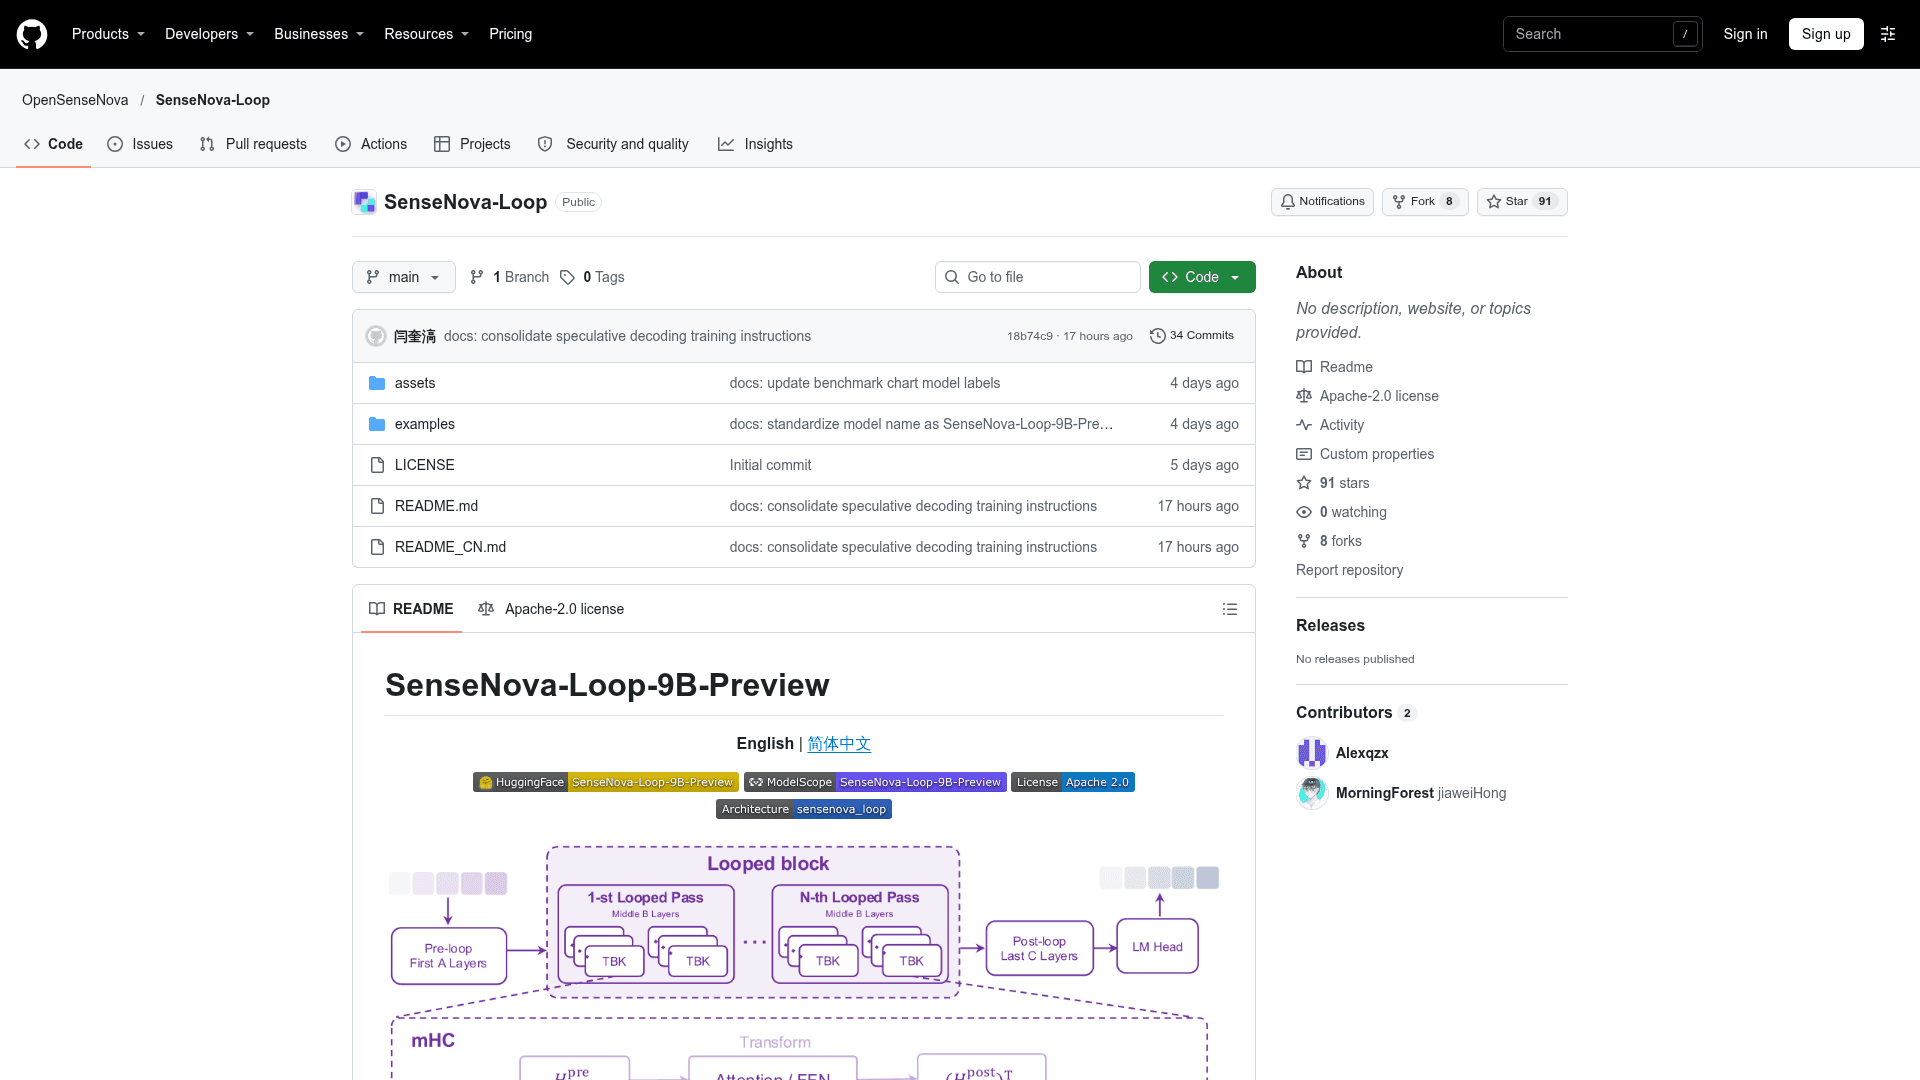
The decoder processes layers 0–3, then applies the shared block of layers 4–27 twice, followed by layers 28–31 and the output head. This yields 56 decoder-layer executions per forward pass while storing 32 distinct layers of weights. Two-stream manifold-constrained hyper-connections (mHC) route information between two residual streams inside the looped section, using Sinkhorn normalization with 20 iterations. The decoder also interleaves three linear-attention layers with one full-attention layer in a repeating four-layer pattern.
Setup and Deployment
The checked inference environment uses Transformers 5.18.0 and PyTorch 2.11.0 with CUDA 13.0, and loading requires trust_remote_code to pull in the custom model implementation. The README gives a single-GPU text generation example with an optional thinking mode. Serving examples cover LightLLM, plus SGLang and vLLM via specific pull requests that include the SenseNova Loop implementation. Fine-tuning (SFT, DPO, MTP) uses a torchtitan-based training guide on a single 8-GPU node.
Inference Acceleration
MTP is available for accelerated inference. Dspark and Dflash2 speculative decoding draft models are listed as training in progress, with training scripts in the SenseSpec repository. The README notes that practical speedups depend on workload, hardware, and serving configuration.
Community Discussions
Be the first to start a conversation about SenseNova-Loop-9B-Preview
Share your experience with SenseNova-Loop-9B-Preview, ask questions, or help others learn from your insights.
Pricing
Open Source (Apache 2.0)
SenseNova-Loop-9B-Preview model and repository released under the Apache License 2.0; self-hosted, no-charge license grant.
- Apache License 2.0
- Multimodal (text and images in, text out) looped decoder model for long-context and agentic workflows
- Weights available on Hugging Face and ModelScope
- Self-hosted; inference and hosting costs are borne by the user
Capabilities
Key Features
- Looped decoder with shared-weight block applied twice (56 layer executions from 32 distinct layers)
- Two-stream manifold-constrained hyper-connections (mHC)
- Hybrid linear and full attention
- Text and image input with text output
- Long-context training up to 262,144 tokens
- MTP inference acceleration
- Transformers inference with optional thinking mode
- Fine-tuning via torchtitan (SFT, DPO, MTP)
- Serving via LightLLM, SGLang, and vLLM