
mlx-optiq
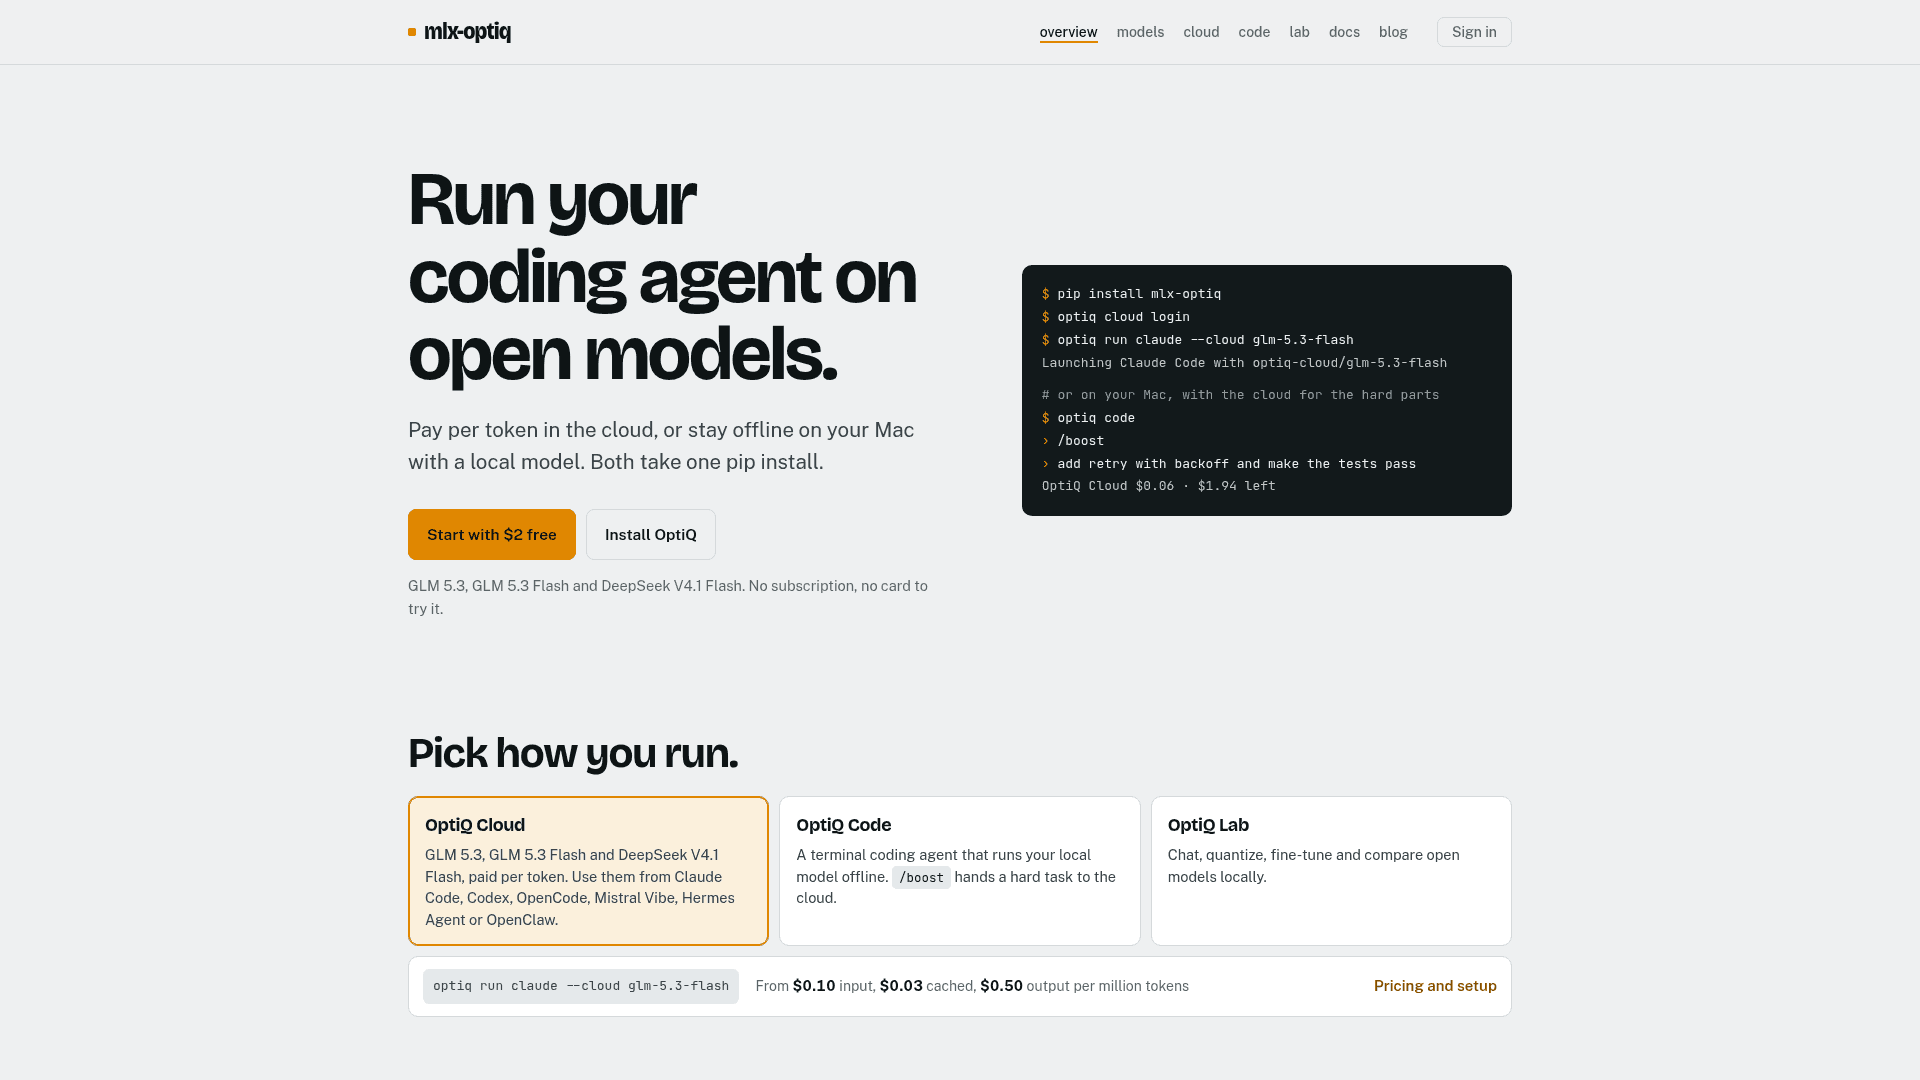
Run coding agents on open models via a pay-per-token cloud or offline on a Mac with local mixed-precision models, installed with one pip package.
At a Glance
Engagement
Available On
Listed Oct 2026
About mlx-optiq
mlx-optiq is a pip-installable toolkit that lets developers run coding agents on open models, either through a per-token cloud service or locally on Apple Silicon Macs. It bundles three products, OptiQ Cloud, OptiQ Code and OptiQ Lab, on top of a shared CLI engine built on Apple MLX and mlx-lm.
What It Is
OptiQ is a set of tools for working with open models. OptiQ Cloud hosts GLM 5.3, GLM 5.3 Flash and DeepSeek V4.1 Flash, which can be used from Claude Code, Codex, OpenCode, Mistral Vibe, Hermes Agent or OpenClaw. OptiQ Code is a terminal coding agent that drives a local or cloud model through a read, edit and run-tests loop. OptiQ Lab is a local web app for chat, quantizing, fine-tuning and building datasets.
The CLI engine
All three products run on the mlx-optiq CLI. It can serve models through OpenAI-compatible and Anthropic-compatible endpoints, convert models into mixed-precision quants by measuring each layer's sensitivity, prune experts from mixture-of-experts models, fine-tune with LoRA, and evaluate quants with a smoketest and a full benchmark suite. The docs say vision input is supported on Gemma-4, Qwen3.5 and Qwen3.6.
Cloud and local workflow
After signing in with optiq cloud login, a single command such as optiq run claude --cloud glm-5.3-flash launches an agent on a cloud model. In OptiQ Code, the /boost command hands a hard task from the local model to the cloud. The vendor reports its own benchmark results, including a 30-task run and an SWE-bench-Lite comparison, on its published pages. The site lists 100+ OptiQ models and 80+ community quants on Hugging Face.
Setup path
The docs say the examples run on a Mac with Python 3.11+ and 16 GB+ RAM. A full library reference is also published as /llms.txt for use in agent context windows.
Community Discussions
Be the first to start a conversation about mlx-optiq
Share your experience with mlx-optiq, ask questions, or help others learn from your insights.
Pricing
GLM 5.3 Flash
OptiQ Cloud pay-per-token model with 1M context
- Input $0.15 per million tokens
- Cached $0.03 per million tokens
- Output $0.50 per million tokens
- Context 1M
DeepSeek V4.1 Flash
OptiQ Cloud pay-per-token model with 1M context
- Input $0.10 per million tokens
- Cached $0.03 per million tokens
- Output $0.50 per million tokens
- Context 1M
GLM 5.3
OptiQ Cloud pay-per-token model with 1M context
- Input $1.40 per million tokens
- Cached $0.26 per million tokens
- Output $4.40 per million tokens
- Context 1M
Capabilities
Key Features
- Pay-per-token cloud access to GLM 5.3, GLM 5.3 Flash and DeepSeek V4.1 Flash
- Run Claude Code, Codex, OpenCode, Mistral Vibe, Hermes Agent or OpenClaw on cloud models
- OptiQ Code terminal coding agent for local models with /boost cloud handoff
- OptiQ Lab local web app for chat, quantizing, fine-tuning and dataset building
- Sensitivity-based mixed-precision quantization
- Mixture-of-experts pruning
- OpenAI- and Anthropic-compatible model server
- LoRA fine-tuning with PEFT-compatible adapters
- Vision image+text support on Gemma-4, Qwen3.5 and Qwen3.6
- Eval CLI with smoketest and full benchmark suite