
TorchAO
PyTorch-native library for quantizing and sparsifying models for training and inference.
At a Glance
About TorchAO
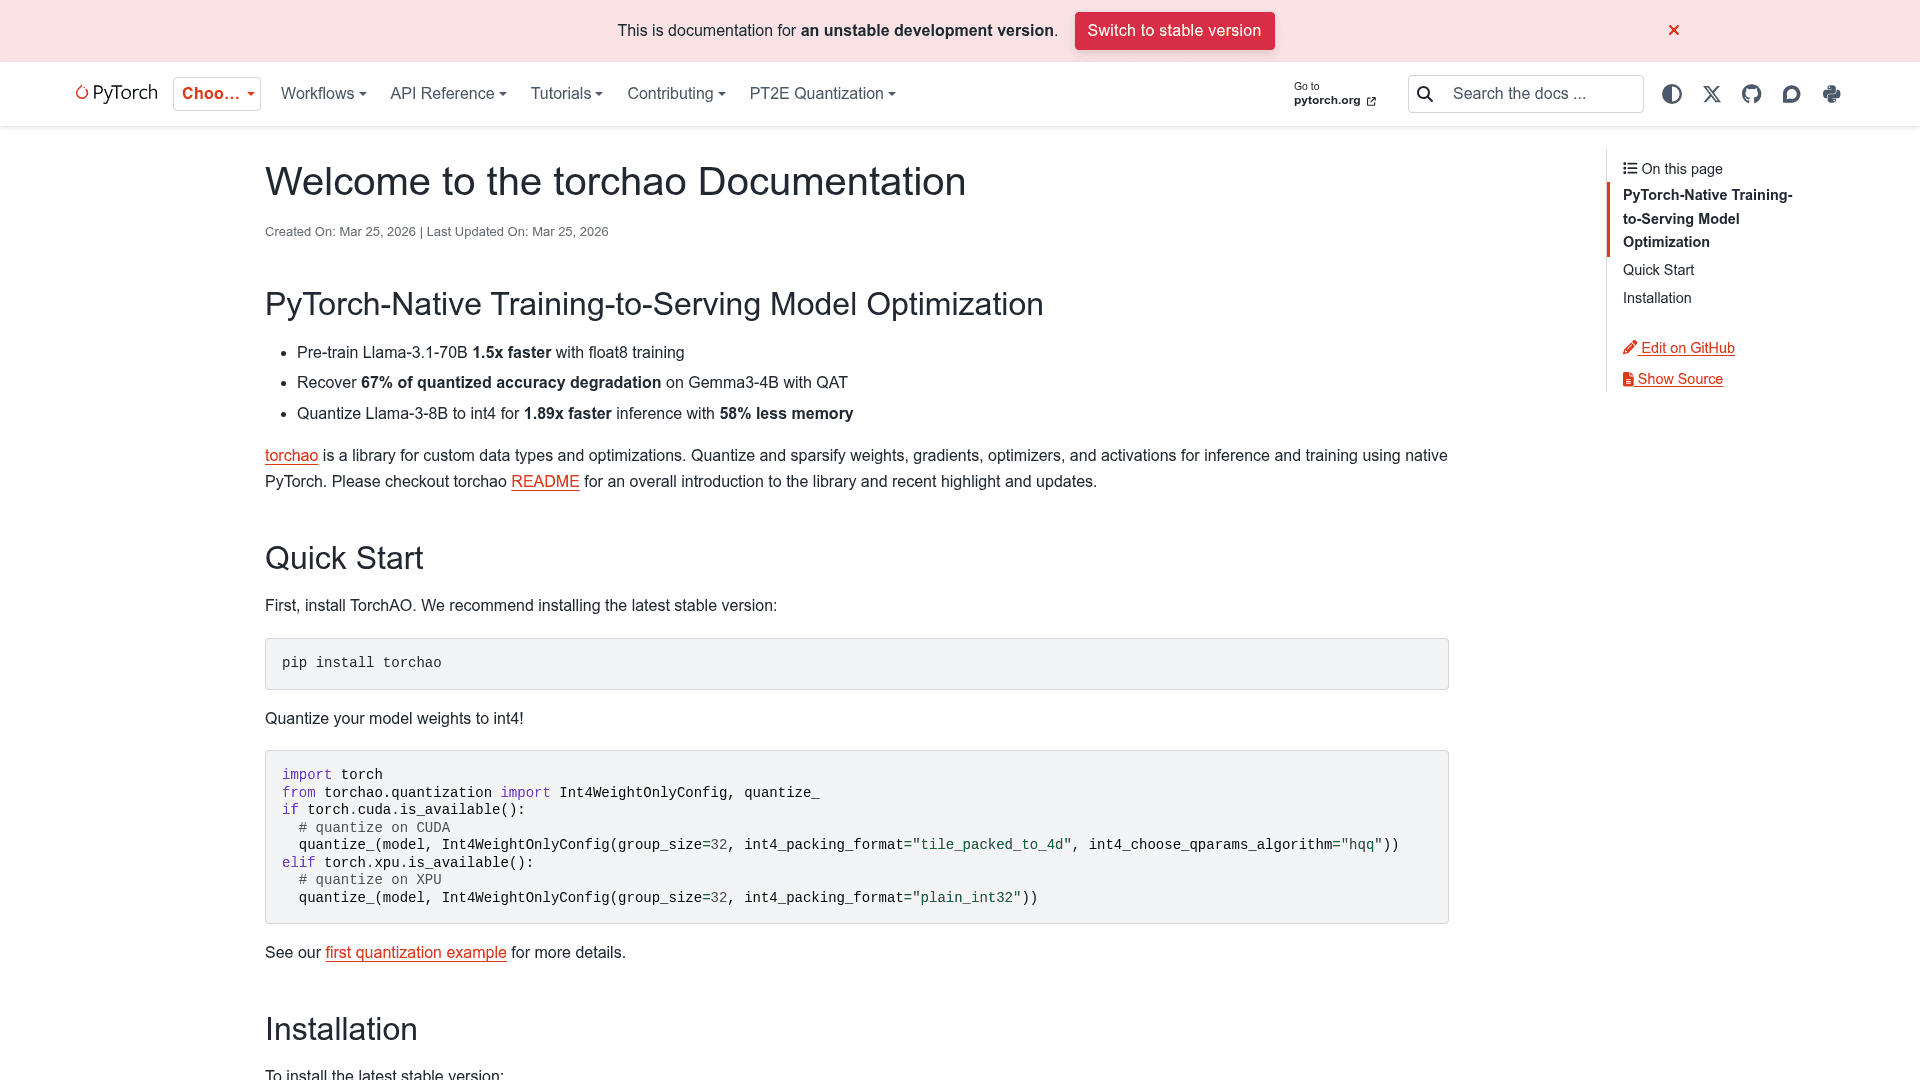
TorchAO is a PyTorch-native library for custom data types and optimizations, hosted under the pytorch GitHub organization. It quantizes and sparsifies weights, gradients, optimizers, and activations for both training and inference. The latest GitHub release listed is v0.18.0, published 2026-08-03.
What It Is
TorchAO is a Python library that adds quantization, quantization-aware training, float8 training, and sparsity to native PyTorch models. The README states it works out of the box with torch.compile() and FSDP2 across most Hugging Face PyTorch models. Users apply it by calling APIs such as quantize_ with a config object (for example an int4 weight-only config), or convert_to_float8_training for float8 training.
Workflows: Training to Serving
The documentation organizes the library into quantized training, quantization-aware training (QAT), and quantized inference. QAT uses a prepare step, a training step, and a convert step to reduce the accuracy loss from low-bit quantization. The project also provides memory-efficient optimizers (8-bit, 4-bit, and fp8 AdamW variants) and CPU offloading of optimizer state. The docs also cover PT2E quantization, static quantization, serialization, and writing custom quantized tensor subclasses.
Integrations and Deployment
The README lists integrations with Hugging Face Transformers, Diffusers, and PEFT, vLLM, SGLang, ExecuTorch for edge devices, TorchTitan, TorchTune, Axolotl, Unsloth, and MSLK kernels. Installation is via pip, with index options for nightly builds, CUDA 12.6 and 12.9, XPU, and CPU-only. The project reports benchmark figures such as 1.5x faster float8 pre-training of Llama-3.1-70B and 1.89x faster int4 inference for Llama-3-8B with 58% less memory.
Community Discussions
Be the first to start a conversation about TorchAO
Share your experience with TorchAO, ask questions, or help others learn from your insights.
Pricing
Open Source
TorchAO core library released under the BSD 3-Clause license (OSI-approved), free to use, modify and redistribute under license terms.
- BSD 3-Clause license (OSI-approved)
- PyTorch-native quantization for training and inference
- Quantization-aware training (QAT)
- Float8 training and sparsity
Capabilities
Key Features
- Int4, int8, and float8 weight and activation quantization
- Quantization-aware training (QAT)
- Float8 and MXFP8 quantized training
- Quantized and CPU-offload memory-efficient optimizers
- Semi-structured and block sparsity
- Works with torch.compile and FSDP2
- PT2E quantization workflows
- Custom quantized tensor subclasses
- Serving via vLLM, SGLang, and ExecuTorch